Operations
Hue Administration
Superusers can open the administration page at http://<hue>/about/. It contains these tabs:
- Overview has three sections:
- Config Status validates your Hue configuration. It lists potential misconfigurations and hints on how to fix them.
- Examples installs examples of SQL tables and queries.
- Analytics turns the collection of anonymous usage analytics on or off.
- Configuration displays the configuration sections of the installed Hue applications.
- Metrics shows the server metrics.
- Server Logs displays the Hue server log.
Configuration
Hue ships with a default configuration that assumes a set of services is present. Customize it for your cluster in a .ini file:
- In the installation directory, edit a file in
desktop/conf, for examplepseudo-distributed.iniwhen you build from source. - If the
HUE_CONF_DIRenvironment variable is set, Hue reads the files in that directory instead.
Click the tabs under Configuration Sections to see the settings of each application. For information on the settings, see Configuration.
Hue loads and merges all the files with the .ini extension in the configuration directory. Files that are alphabetically later take precedence.
After editing an .ini file, restart Hue.
Configuration validation
To view the configuration of a running Hue instance, go to:
http://<hue>/desktop/dump_config
The page shows the location of the configuration files and all the configuration values, with their help and default values.
To list all the available configuration options on the command line, run:
build/env/bin/hue config_help | less
Server logs
The Server Logs tab displays the Hue server log. You can download the logs to your computer in a zip file.
Metrics
Hue uses the PyFormance Python library to collect metrics. The metrics are gauges, counters, meters (rate of events over time), and histograms (statistical distribution of values). The /desktop/metrics/ endpoint returns all the metrics as JSON.
The Metrics tab shows, among others:
requests.activerequests.exceptionsrequests.response-timethreads.daemonthreads.totalusersusers.active
The most useful ones are the percentiles of the request response time and the count of active users. You can filter a property across all the metrics, or select a metric to see all its properties.
Logging
The Hue logs are in the logs directory under your Hue installation root. To use another directory, start the supervisor with the --log-dir option. The log directory contains:
access.log: all the requests against the Hue web server.supervisor.log: the log of the supervisor process.supervisor.out: the stdout and stderr of the supervisor process.- A
.logfile for each supervised process: the logs of that process. - A
.outfile for each supervised process: the stdout and stderr of that process.
If users have problems running Hue, you can often find error messages in these log files. If you cannot start Hue, the supervisor.log file can contain clues.
Besides logging INFO level messages to the logs directory, the Hue web server keeps a small buffer of log messages at all levels in memory. To view them, go to http://myserver:8888/logs. The DEBUG level messages can help you troubleshoot.
Commands
Commands are utilities for tasks like changing a user password, creating a superuser, and cleaning up old sessions and documents.
Run the commands from the Hue installation root. For example:
cd /usr/share/hue
To list all the available commands:
build/env/bin/hue
To get help on a command:
build/env/bin/hue help <command>
Commonly used commands:
| Command | Description |
|---|---|
changepassword |
Change the password of a user |
createsuperuser |
Create a superuser |
migrate |
Create or update the database tables |
dumpdata, loaddata |
Export and import data as JSON |
dbshell |
Open the shell of the Hue database |
shell |
Open a Python shell with Hue loaded |
config_help |
List all the configuration options |
desktop_document_cleanup |
Delete old documents |
clearsessions |
Delete expired sessions |
close_queries, close_sessions |
Close old Hive queries and sessions |
sync_ldap_users_and_groups, import_ldap_user, import_ldap_group |
Import and sync users and groups from LDAP |
is_db_alive |
Check that the Hue database is reachable |
version |
Print the Hue version |
Troubleshooting
Instrumentation
To find out why Hue is slow or uses a lot of memory, set the instrumentation flag to true:
[desktop]
instrumentation=true
If django_debug_mode is enabled, instrumentation is enabled automatically. The flag appends the response time and the peak memory used since Hue started to every logged request.
Instrumentation enabled:
[17/Apr/2018 15:18:43 -0700] access INFO 127.0.0.1 admin - "POST /jobbrowser/jobs/ HTTP/1.1" `returned in 97ms (mem: 135mb)`
Instrumentation not enabled:
[23/Apr/2018 10:59:01 -0700] INFO 127.0.0.1 admin - "POST /jobbrowser/jobs/ HTTP/1.1" returned in 88ms
Change or reset a password
To change the password of a user, run the changepassword command. It uses the currently logged in Unix user when you omit the username:
build/env/bin/hue changepassword [username]
If you do not remember the admin username, create a new Hue admin. You can then log in and change the password of another user in Hue:
build/env/bin/hue createsuperuser
Make a user an admin
As an admin, use the Admin UI.
If this is not possible (for example when nobody is admin), use the command line as explained in the examples of the Python API.
As a last resort, update the user records in the database with SQL.
Export documents
Export all documents:
./build/env/bin/hue dumpdata desktop.Document2 --indent 2 --natural > data.json
Export specific documents:
20000013 is the ID that you can see in the URL of the document.
./build/env/bin/hue dumpdata desktop.Document2 --indent 2 --pks=20000013 --natural > data.json
To export more than one document, list several IDs:
--pks=20000013,20000014,20000015
Load the documents:
./build/env/bin/hue loaddata data.json
Large downloads
Downloading and exporting results does not scale well unless the Task Server is enabled. Restrict the number of rows or bytes transferred with the download options in your hue.ini.
Slow because of too many documents
Too many entries in the database cause performance issues. The configuration check warns superusers about it: log in as a superuser and open Hue Administration.
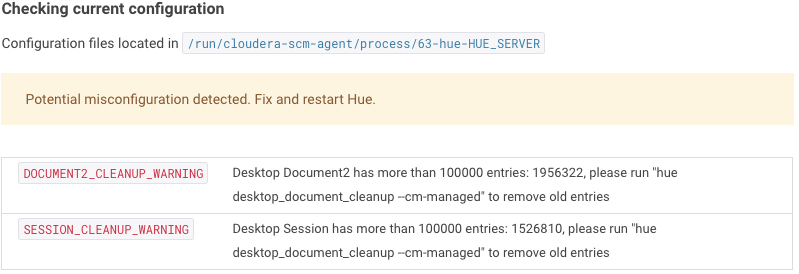
To clean up the Hue database, go to the Hue directory and run:
./build/env/bin/hue desktop_document_cleanup
Too many connections
When getting an error similar to OperationalError: (1040, 'Too many connections'), the Hue database is out of connections. Hue only needs 2 connections, but other services that use the same database can take them all. Increase max_connections to around 1000. For example, in MySQL:
SET GLOBAL max_connections = 1000;
Test a SQL connection from a pod
-
Check your Hive version in the SQL Editor:
SELECT version()Example result:
2.3.2 r857a9fd8ad725a53bd95c1b2d6612f9b1155f44d -
List the Hue pods:
kubectl get podsExample output:
NAME READY STATUS RESTARTS AGE hue-758466dc77-wpcx8 2/2 Running 0 22h ingress-nginx-controller-5d6fbbddb6-8kd86 1/1 Running 0 23h postgres-hue-64c9cc8744-dpk47 1/1 Running 1 47d -
Open a shell in the Hue pod:
kubectl exec -it hue-758466dc77-wpcx8 -- bash -
Download the Hadoop and Hive client files of the same version as your Hive from Hadoop and Hive, and set the environment:
wget https://archive.apache.org/dist/hadoop/core/hadoop-2.7.4/hadoop-2.7.4.tar.gz wget https://archive.apache.org/dist/hive/hive-2.3.2/apache-hive-2.3.2-bin.tar.gz tar -xvzf hadoop-2.7.4.tar.gz tar -xvzf apache-hive-2.3.2-bin.tar.gz export HADOOP_HOME=`pwd`/hadoop-2.7.4 export HIVE_HOME=`pwd`/apache-hive-2.3.2-bin export JAVA_HOME=/usr/lib/jvm/java-1.11.0-openjdk-amd64 export PATH=$PATH:$HIVE_HOME/bin -
Connect with Beeline:
beeline -u 'jdbc:hive2://172.21.0.3:10000'Example output:
Connecting to jdbc:hive2://172.21.0.3:10000
Connected to: Apache Hive (version 2.3.2)
Driver: Hive JDBC (version 2.3.2)
Transaction isolation: TRANSACTION_REPEATABLE_READ
Beeline version 2.3.2 by Apache Hive
0: jdbc:hive2://172.21.0.3:10000> SHOW TABLES;
+--------------------+
|      tab_name      |
+--------------------+
| customers          |
| web_logs           |
+--------------------+
Read more on the Hive wiki about the beeline command line.
Scripts
For building custom scripts for managing objects like users or saved documents, check out the Python API.
Database
See the dedicated Database section.