Reference
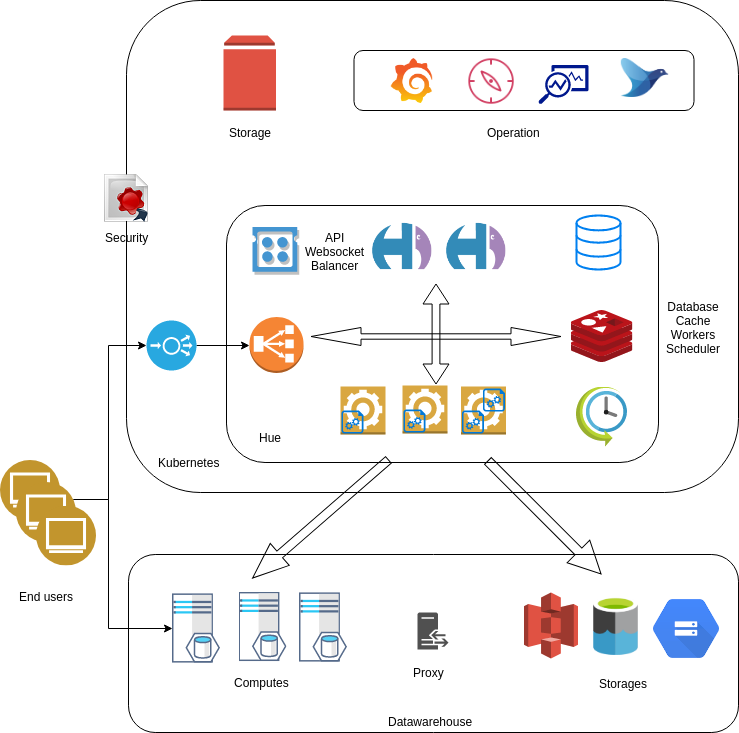
A recommended setup consists of:
- 2 Hue servers and 1 load balancer
- A database: MySQL InnoDB, PostgreSQL, or Oracle
- Authentication: LDAP or username/password
Typical setups range from 2 to 5 Hue servers. For example, 3 Hue servers can serve 300+ unique users, with peaks of 125 users per hour and 300 queries.
As a rule of thumb, plan for about 50 users per Hue server at peak time. This accounts for worst-case scenarios. Most scale issues come from resource-intensive operations, like large downloads of query results, or from slow calls from Hue to a service (for example, submitting a query hangs when Hive is slow), not from the number of users. The Task Server is a beta feature that moves such operations out of the API server.
Performance
General
-
Put Hue behind a load balancer that proxies the static files. For example, NGINX is used for the containers.
-
Each additional Hue instance behind the load balancer supports about 50 more concurrent users.
-
Use a database like MySQL, PostgreSQL, or Oracle. Hue does not work well on SQLite because it makes concurrent write calls to the database.
-
Check the number of documents in the Hue database. If there are too many (more than 100 000), delete the old records. Stop Hue, go to the Hue installation directory, and run the following command:
./build/env/bin/hue desktop_document_cleanup -
Python has memory fragmentation issues that show up in Hue. Check the memory usage of Hue periodically. Browsing HDFS directories with many files, downloading a query result, and copying HDFS files are costly operations memory-wise.
The Config Status section of Hue Administration (/about/) warns about detected risks. Make sure it reports no warnings.
Hue caches SQL metadata throughout the application. The list of tables of a database or the columns of a table are fetched once and reused in the autocomplete, the table browser, and the left and right panels. The logs include the total time taken by each request.
For example:
[24/Jul/2019 14:17:32 +0000] resource     DEBUG    GET /jobs Got response in 151ms: {"total":0,"offset":1,"len":1,"coordinatorjobs":[]}
[24/Jul/2019 14:17:32 +0000] access       INFO     127.0.0.1 romain - "POST /jobbrowser/api/jobs HTTP/1.1" returned in 157ms (mem: 164mb)
Query Editor
- Compare the performance of the Hive Query Editor in Hue with the same query in a Beeline shell against the same HiveServer2 instance. This shows whether to investigate Hue or HiveServer2.
- Check the logging level of HiveServer2. Make sure it is not set to
DEBUGorTRACE. If it is, set it toINFOat a minimum. - Configure a dedicated HiveServer2 instance for each Hue instance, separate from the HiveServer2 instances used by other tools or clients. Or configure Hue to point to multiple HiveServer2 instances behind a load balancer.
- Tune the query timeouts of HiveServer2 (in
hive-site.xml) and Impala (in thehue.ini). See Queries life cycle.
Downloading more than a few thousand rows lags and increases the CPU and memory usage of Hue a lot. For this reason, the results are truncated.
Load Balancers
Hue is often run with:
- CherryPy with NGINX (recommended)
- CherryPy with Apache HTTPD
- Gunicorn
Queries life cycle
Each query uses resources in Impala or HiveServer2. When users submit many queries, the resources add up and can crash the servers if nothing is done. These settings control how long queries and their results are kept.
Impala
By default, Hue closes the Impala query when the user leaves the result page (close_queries=true). If the user never closes the page, the query stays open. Impala cancels the queries that are idle for longer than query_timeout_s.
[impala]
# If > 0, the query will be timed out (i.e. cancelled) if Impala does not do any work
# (compute or send back results) for that query within QUERY_TIMEOUT_S seconds.
query_timeout_s=300

# If > 0, the session will be timed out (i.e. cancelled) if Impala does not do any work
# (compute or send back results) for that session within SESSION_TIMEOUT_S seconds (default 15 minutes).
session_timeout_s=900
Note: Impala only cancels the idle query. It does not close it. To close idle sessions, set
-idle_session_timeout=20in the Impala flags. Hue also has asession_timeout_ssetting.
Hive
By default, Hue does not close Hive queries, because some queries take hours. If your query volume is low (fewer than a few hundred a day) and you restart HiveServer2 every week, you are probably not affected. To close the query when the user leaves the page, like for Impala, set this in the hue.ini:
[beeswax]
# Hue will try to close the Hive query when the user leaves the editor page.
# This will free all the query resources in HiveServer2, but also make its results inaccessible.
close_queries=true
The close_queries and close_sessions commands close old Hive queries and sessions. Both take an optional age in days (default is 7) and an optional all keyword:
build/env/bin/hue close_queries [age_in_days] [all]
build/env/bin/hue close_sessions [age_in_days] [all]
close_queriescloses the expired, failed and finished queries older than the given age. Withall, it closes the queries whatever their state.close_sessionscloses the Beeswax sessions older than the given age. Withall, it closes the sessions of all the applications.
Run build/env/bin/hue close_queries --help to see all the options.
Export HIVE_CONF_DIR (for example /etc/hive/conf) before you run the commands. Export HUE_CONF_DIR too if your Hue configuration is not in desktop/conf.
For example, to close the finished queries and all the sessions older than 0 days:
./build/env/bin/hue close_queries 0
./build/env/bin/hue close_sessions 0 all
Closing (all=False) HiveServer2 queries older than 0 days...
1 queries closed. 0 queries already closed.
Closing (all=True) HiveServer2 sessions older than 0 days...
Found 1 open HiveServer2 sessions to close
1 sessions closed.
0 sessions skipped because already closed.
Add these commands to a crontab to expire the queries older than N days.
Like Impala, HiveServer2 can expire queries automatically. Set these properties in hive-site.xml:
<property>
  <name>hive.server2.session.check.interval</name>
  <value>3000</value>
  <description>The check interval for session/operation timeout, which can be disabled by setting to zero or negative value.</description>
</property>

<property>
  <name>hive.server2.idle.session.timeout</name>
  <value>3000</value>
  <description>Session will be closed when it's not accessed for this duration, which can be disabled by setting to zero or negative value.</description>
</property>

<property>
  <name>hive.server2.idle.operation.timeout</name>
  <value>0</value>
  <description>Operation will be closed when it's not accessed for this duration of time, which can be disabled by setting to zero value. With positive value, it's checked for operations in terminal state only (FINISHED, CANCELED, CLOSED, ERROR). With negative value, it's checked for all of the operations regardless of state</description>
</property>
Note: This is the recommended solution for Hive. To keep results for longer, use
CREATE TABLE AS SELECTor export the results in Hue.
Impala and Hive HA
This section describes how to configure your analytic database for high availability with Hue and other SQL clients.
HiveServer2 and Impala support High Availability through a “load balancer”. One caveat is that Hue's underlying Thrift libraries reuse TCP connections in a pool, a single user session may not have the same Impala or Hive TCP connection. If a TCP connection is balanced away from the previously selected HiveServer2 or Impalad instance, the user session and its queries can be lost and trigger the “Results have expired” or “Invalid session Id” errors.
To prevent sessions from being lost, we need configure the load balancer with “source” algorithm to ensure each Hue instance sends all traffic to a single HiveServer2/Impalad instance. Yes, this is not true load balancing, but a configuration for failover High Availability. HiveSever2 or Impala coordinators already distribute the work across the cluster so this is not an issue.
To enable an optimal load distribution that works for everybody, we can create multiple profiles in our load balancer, per port for Hue clients and non-Hue clients like Hive or Impala. We can configure non-Hue clients to distribute loads with “roundrobin” or “leastconn” and configure Hue clients with “source” (source IP Persistence) on dedicated ports, for example, 10015 for Hive beeline commands, 10016 for Hue, 21051 for Hue-Impala interactions while 25003 for Impala shell.
As shown in above diagram, you can configure the HaProxy to have two different ports associated with different load balancing algorithms. Here is a sample configuration (haproxy.cfg) for Hive and Impala HA on a secure cluster.
#-----------------------
# main frontend which proxys to the backends
#-----------------------
frontend hiveserver2_front
bind *:10015 ssl crt /path/to/cert_key.pem
mode tcp
option tcplog
default_backend hiveserver2
#-----------------------
# round robin balancing between the various backends
#-----------------------
# This is the setup for HS2. beeline client connect to load_balancer_host:load_balancer_port.
# HAProxy will balance connections among the list of servers listed below.
backend hiveserver2
balance roundrobin
mode tcp
server hiveserver2_1 host-2.com:10000 ssl ca-file /path/to/truststore.pem check
server hiveserver2_2 host-3.com:10000 ssl ca-file /path/to/truststore.pem check
server hiveserver2_3 host-1.com:10000 ssl ca-file /path/to/truststore.pem check

# Setup for Hue or other JDBC-enabled applications.
# In particular, Hue requires sticky sessions.
# The application connects to load_balancer_host:10016, and HAProxy balances
# connections to the associated hosts, where Hive listens for JDBC requests on port 10015.
#-----------------------
# main frontend which proxys to the backends
#-----------------------
frontend hivejdbc_front
bind *:10016 ssl crt /path/to/cert_key.pem
mode tcp
option tcplog
stick match src
stick-table type ip size 200k expire 30m
default_backend hivejdbc

#-----------------------
# source balancing between the various backends
#-----------------------
# HAProxy will balance connections among the list of servers listed below.
backend hivejdbc
balance source
mode tcp
server hiveserver2_1 host-2.com:10000 ssl ca-file /path/to/truststore.pem check
server hiveserver2_2 host-3.com:10000 ssl ca-file /path/to/truststore.pem check
server hiveserver2_3 host-1.com:10000 ssl ca-file /path/to/truststore.pem check
And here is an example for Impala HA configuration on a secure cluster.
# The list of Impalad is listening at port 21000 for beeswax (impala-shell) or original ODBC driver.
# For JDBC or ODBC version 2.x driver, use port 21050 instead of 21000.
#-----------------------
# main frontend which proxys to the backends
#-----------------------
frontend impala_front
bind *:25003 ssl crt /path/to/cert_key.pem
mode tcp
option tcplog
default_backend impala
#-----------------------
# round robin balancing between the various backends
#-----------------------
backend impala
balance leastconn
mode tcp
server impalad1 host-3.com:21000 ssl ca-file /path/to/truststore.pem check
server impalad2 host-2.com:21000 ssl ca-file /path/to/truststore.pem check
server impalad3 host-4.com:21000 ssl ca-file /path/to/truststore.pem check

# Setup for Hue or other JDBC-enabled applications.
# In particular, Hue requires sticky sessions.
# The application connects to load_balancer_host:21051, and HAProxy balances
# connections to the associated hosts, where Impala listens for JDBC requests on port 21050.
#-----------------------
# main frontend which proxys to the backends
#-----------------------
frontend impalajdbc_front
bind *:21051 ssl crt /path/to/cert_key.pem
mode tcp
option tcplog
stick match src
stick-table type ip size 200k expire 30m
default_backend impalajdbc
#-----------------------
# source balancing between the various backends
#-----------------------
# HAProxy will balance connections among the list of servers listed below.
backend impalajdbc
balance source
mode tcp
server impalad1 host-3.com:21050 ssl ca-file /path/to/truststore.pem check
server impalad2 host-2.com:21050 ssl ca-file /path/to/truststore.pem check
server impalad3 host-4.com:21050 ssl ca-file /path/to/truststore.pem check
Note: “check” is required at end of each line to ensure HaProxy can detect any unreachable Impalad/HiveServer2 server, so HA failover can be successful. Without TCP check, you may hit the “TSocket reads 0 byte” error when the Impalad/HiveServer2 server Hue tries to connect is down.
After editing the /etc/haproxy/haproxy.cfg file, run following commands to restart HaProxy service and check the service restarts successfully.
service haproxy restart
service haproxy status
[impala]
server_port=21051

[beeswax]
hive_server_port=10016
Monitoring
A GET /desktop/debug/is_alive request returns a 200 response when Hue is running.
Behind a Proxy
A web proxy centralizes the access to a URL and gives Hue a friendlier address. For example:
ec2-54-247-321-151.compute-1.amazonaws.com --> demo.gethue.com
You can set it up with NGINX or Apache.
Task Server
Note: The task server is a beta feature.
The task server moves blocking or resource-intensive operations out of the API server. Follow #1526 for the progress.
Prerequisites
Install and run Redis:
sudo apt-get install redis-server -y
Configure the task server
In the hue.ini, tell the API server that the task server is available. Point the broker to Redis:
[desktop]
[[task_server_v2]]
enabled=true
broker_url=redis://localhost:6379/0
Start the task server:
./build/env/bin/celery -A desktop worker -l info
Tasks
Query Task
When the task server is enabled, SQL queries are submitted outside of the Hue servers.
To configure the storage that persists the results, edit the result_storage setting:
[desktop]
[[task_server_v2]]
result_storage='{"backend": "django.core.files.storage.FileSystemStorage", "properties": {"location": "/var/lib/hue/query-results"}}'
Task Scheduler
For schedules configured statically in Python:
./build/env/bin/celery -A desktop beat -l info
For schedules configured dynamically via a table with Django Celery Beat:
[desktop]
[[task_server_v2]]
beat_enabled=true
Then:
./build/env/bin/celery -A desktop beat -l info --scheduler django_celery_beat.schedulers:DatabaseScheduler
Note: the first time the tables need to be created with:
./build/env/bin/hue migrate
Flower
Web UI to monitor tasks:
./build/env/bin/pip install flower
./build/env/bin/celery flower --broker=redis://localhost:6379/0
Then open-up http://localhost:5555/tasks