Connectors
Configuration
Config file
Hue connects to any database or warehouse via native Thrift, SQLAlchemy or JDBC connectors. Add them to the hue.ini file. Except for [impala] and [beeswax], which have a dedicated section, add each connector below [[interpreters]] in the [notebook] section, for example:
[notebook]
[[interpreters]]

[[[mysql]]]
name=MySQL
interface=sqlalchemy
options='{"url": "mysql://user:password@localhost:3306/hue"}'

[[[presto]]]
name = Presto
interface=sqlalchemy
options='{"url": "presto://localhost:8080/hive/default"}'
Hue can prompt users for their credentials. Use the ${USER} and ${PASSWORD} variables, for example mysql://${USER}:${PASSWORD}@localhost:3306/hue.
Most interpreters require you to install their SQLAlchemy dialect, for example ./build/env/bin/pip install pyhive. Install it in the global Python environment or in the Hue virtual environment.
To get better autocomplete for your SQL dialect, read how to build your own parser.
Connectors
Admins can configure the connectors via the UI or the REST API. This feature is off by default. Enable it with the enable_connectors and enable_hue_5 flags:
[desktop]
enable_connectors=true
enable_hue_5=true
Note: After you enable these flags, you might get the error
django.db.utils.OperationalError: (1054, "Unknown column 'useradmin_huepermission.connector_id' in 'field list'"). There is no upgrade path for this change. Change the database name under[[database]]in hue.ini, then run./build/env/bin/hue migrate.
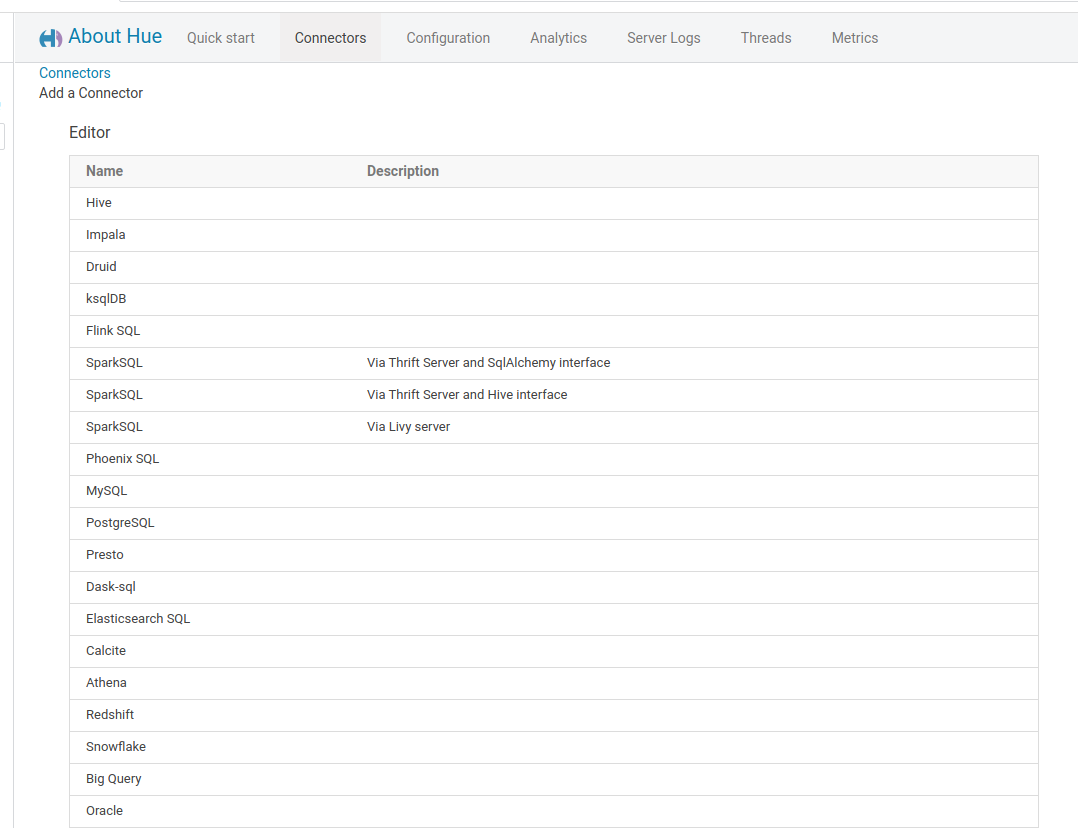
Go to Administer Server > Connectors > + Connector, or open http://127.0.0.1:8000/hue/desktop/connectors.
Databases
The following sections list the supported databases and their configuration.
Apache Hive
The developer documentation shows how to set up a Hive test environment.
Support is native via a dedicated section.
[beeswax]
# Host where HiveServer2 is running.
# If Kerberos security is enabled, use fully-qualified domain name (FQDN).
hive_server_host=localhost

# Port where HiveServer2 Thrift server runs on.
hive_server_port=10000
Read more about LDAP or PAM pass-through authentication and High Availability.
Note: For historical reasons, the configuration section is named
[beeswax].
Tez
Requires support for sending multiple queries when using Tez (instead of a maximum of just one at the time). You can turn it on with this setting:
[beeswax]
max_number_of_sessions=3
LLAP
When the LLAP interpreter is added, there are 2 ways to enable connectivity (direct configuration or service discovery). LLAP is added by enabling the following settings:
[notebook]
[[interpreters]]
[[[llap]]]
name=LLAP
interface=hiveserver2

[beeswax]
# Direct Configuration
llap_server_host = localhost
llap_server_port = 10500
llap_server_thrift_port = 10501

# or Service Discovery
## hive_discovery_llap = true
## hive_discovery_llap_ha = false
# Shortcuts to finding LLAP znode Key
# Non-HA - hiveserver-interactive-site - hive.server2.zookeeper.namespace ex hive2 = /hive2
# HA-NonKerberized - <llap_app_name>_llap ex app name llap0 = /llap0_llap
# HA-Kerberized - <llap_app_name>_llap-sasl ex app name llap0 = /llap0_llap-sasl
## hive_discovery_llap_znode = /hiveserver2-hive2
Service Discovery
When service discovery is enabled, Hue queries ZooKeeper to find an enabled HiveServer2 or LLAP endpoint.
[beeswax]
hive_discovery_llap = true
hive_discovery_hs2 = true
To avoid flooding ZooKeeper, Hue caches the HiveServer2 endpoint for the life of the process. It caches the LLAP endpoint for the number of seconds set by cache_timeout:
[beeswax]
cache_timeout = 60
HPL/SQL
HPL/SQL is an Apache open source procedural extension for SQL for Hive users. This HPL/SQL Editor post demoes the integration.
[[[hplsql]]]
name=Hplsql
interface=hiveserver2
Note:
- HPL/SQL uses the
[beeswax]config like Hive uses.- In HPL/SQL mode, end commands with a forward slash (
/). The semicolon (;) is used inside procedure declarations, so it can't terminate a query in the editor.
Apache Impala
This Impala SQL Editor post demoes the integration.
Support is native via a dedicated section.
[impala]
# Host of the Impala Server (one of the Impalad)
server_host=localhost

# Port of the Impala Server
server_port=21050
Read more about LDAP or PAM pass-through authentication and High Availability.
MySQL
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install mysqlclient
Then give Hue the information about the database source:
[[[mysql]]]
name=MySQL
interface=sqlalchemy
options='{"url": "mysql://root:root@localhost:3306/hue"}'
## mysql://${USER}:${PASSWORD}@localhost:3306/hue
Query string options are documented in the SqlAlchemy MySQL documentation.
Alternative:
[[[mysqljdbc]]]
name=MySql JDBC
interface=jdbc
## Specific options for connecting to the server.
## The JDBC connectors, e.g. mysql.jar, need to be in the CLASSPATH environment variable.
## If 'user' and 'password' are omitted, they will be prompted in the UI.
options='{"url": "jdbc:mysql://localhost:3306/hue", "driver": "com.mysql.jdbc.Driver", "user": "root", "password": "root"}'
## options='{"url": "jdbc:mysql://localhost:3306/hue", "driver": "com.mysql.jdbc.Driver"}'
Presto
Presto has been forked into Trino and both share the same configuration.
To switch between them, replace presto with trino or vice versa.
Trino
Hue uses the official Trino Python client. Hue pins version 0.329.0 of the trino package. To install it manually, run:
./build/env/bin/pip install trino
Then give Hue the information about the Trino cluster:
[[[trino]]]
name=Trino
interface=trino
options='{"url": "http://localhost:8080"}'
To use basic authentication (LDAP or password file), set the credentials. Trino only accepts them over HTTPS, so Hue ignores them and logs a warning for http:// URLs:
options='{"url": "https://trino.example.com:443", "auth_username": "hue", "auth_password": "secret"}'
To avoid storing the password in the configuration, use a password script. Hue uses the script output as the password:
options='{"url": "https://trino.example.com:443", "auth_username": "hue", "auth_password_script": "/path/to/script"}'
Other options:
| Option | Default | Description |
|---|---|---|
ssl_verify |
true |
Validate the server certificate. Use false to disable it, or the path of a CA bundle. |
trino_user |
the Hue user | User sent to Trino (X-Trino-User). |
Databases are listed per catalog and named catalog.schema, e.g. hive.default.
Note:
- Hue supports only basic authentication or unsecured connections.
- The section name must be
trinofor the native client (interface=trino). The SQLAlchemytrino://URL of theinterface=sqlalchemyconnector is a different integration.
Custom connectors
API clients can send a snippet of type custom that defines its own interface and options, which lets the Hue server connect to any host. This is disabled by default. Enable it only if you trust your users:
[notebook]
enable_custom_connectors=true
Connectors defined in the configuration are not affected.
Oracle
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install cx_Oracle
Then give Hue the information about the database source:
[[[oracle]]]
name = Oracle
interface=sqlalchemy
options='{"url": "oracle://user:password@localhost"}'
PostgreSQL
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install psycopg2
  or
./build/env/bin/pip install psycopg2-binary
Then give Hue the information about the database source:
[[[postgresql]]]
name = PostgreSql
interface=sqlalchemy
options='{"url": "postgresql+psycopg2://user:password@localhost:31335/database"}'
AWS Athena
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install PyAthena
Then give Hue the information about the database source:
[[[athena]]]
name = AWS Athena
interface=sqlalchemy
options='{"url": "awsathena+rest://${AWS_ACCESS_KEY_ID}:${AWS_SECRET_ACCESS_KEY}@athena.${REGION}.amazonaws.com:443/${SCHEMA}?s3_staging_dir=${S3_BUCKET_DIRECTORY}&work_group=${WORK_GROUP}&catalog_name=${CATALOG_NAME}"}'
e.g.
options='{"url": "awsathena+rest://XXXXXXXXXXXXXXXXXXXX:XXXXXXXXXXXXXXXXXXXXXXXXXXXXXXXXXXXXXXXX@athena.us-west-2.amazonaws.com:443/default?s3_staging_dir=s3://gethue-athena/scratch&work_group=demo_group&catalog_name=AwsDataCatalog"}'
Note: Keys and S3 buckets need to be URL quoted. Hue does it automatically.
Apache Phoenix
This Phoenix SQL Editor post demoes the integration.
Hue already ships the official Phoenix dialect. To update it yourself, run:
./build/env/bin/pip install phoenixdb
Then give Hue the information about the database source:
[[[phoenix]]]
name=HBase Phoenix
interface=sqlalchemy
options='{"url": "phoenix://sql-phoenix.gethue.com:8765/"}'
If using security:
[[[phoenix]]]
name=HBase Phoenix
interface=sqlalchemy
options='{"url": "phoenix://sql-phoenix.gethue.com:8765", "tls": true, "connect_args": {"authentication": "SPNEGO", "verify": false }}'
Grant the appropriate hbase rights to the ‘hue’ user, e.g.:
grant 'hue', 'RWXCA'
With impersonation:
options='{"url": "phoenix://sql-phoenix.gethue.com:8765", "has_impersonation": true}'
Notes
-
Existing HBase tables need to be mapped to views.
CREATE VIEW IF NOT EXISTS "analytics_demo_view" ( pk VARCHAR PRIMARY KEY, "hours"."01-Total" VARCHAR ); -- Error: ERROR 505 (42000): Table is read only. (state=42000,code=505) -- Create a table instead: CREATE TABLE IF NOT EXISTS "analytics_demo" ( pk VARCHAR PRIMARY KEY, "hours"."01-Total" VARCHAR ); -
Phoenix sees unquoted table names as uppercase. When getting started, create the table via Phoenix.
-- Error: ERROR 1012 (42M03): Table undefined. tableName=ANALYTICS_DEMO (state=42M03,code=1012) -- Quote the table name: SELECT * FROM "analytics_demo" WHERE pk = 'domain.0' LIMIT 5; -
Phoenix follows Apache Calcite. You can help improve the SQL autocomplete support for it.
-
The UI (and the underlying SQLAlchemy API) cannot distinguish between ‘ANY namespace’ and ‘empty/Default’ namespace
Apache Druid
This Druid SQL Editor post demoes the integration.
First, make sure that Hue can talk to Druid via the pydruid SqlAlchemy connector.
./build/env/bin/pip install pydruid
In the hue.ini configuration file, now let's add the interpreter. Here ‘druid-host.com’ would be the machine where Druid is running.
[notebook]
[[interpreters]]
[[[druid]]]
name = Druid
interface=sqlalchemy
options='{"url": "druid://druid-host.com:8082/druid/v2/sql/?header=true"}'
The ?header=true option requires Druid 13.0 or later.
Add the +https prefix to use HTTPS, for example:
druid+https://druid-host.com:8082/druid/v2/sql/?header=true
Apache Flink
This Flink Stream SQL Editor post demoes the integration.
The dialect currently requires the Flink SQL Gateway in order to submit queries.
Then add a Flink interpreter in the Hue configuration:
[notebook]

[[interpreters]]

[[[flink]]]
name=Flink
interface=flink
options='{"url": "http://172.18.0.7:8083"}'
ksqlDB
This ksqlDB Stream SQL Editor post demoes the integration.
The ksql Python module should be added to the system or Hue Python virtual environment:
./build/env/bin/pip install ksql
Then give Hue the information about the interpreter and ksqlDB server. To add to the list of interpreters:
[[[ksqlDB]]]
name=ksqlDB
interface=ksql
options='{"url": "http://ksqldb-server:8088"}'
Google BigQuery
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install pybigquery
./build/env/bin/pip install pyasn1==0.4.1
From https://github.com/mxmzdlv/pybigquery.
Then give Hue the information about the database source:
[[[bigquery]]]
name = BigQuery
interface=sqlalchemy
options='{"url": "bigquery://project-XXXXXX", "credentials_json": "{\"type\": \"service_account\", ...}"}'
Where to get the Json credentials? By creating a service account:
- https://googleapis.dev/python/google-api-core/latest/auth.html
- https://console.cloud.google.com/iam-admin/serviceaccounts
Where to get the names? In the ‘Resources’ panel of Big Query UI:
- Project name, e.g. project-XXXXXX, bigquery-public-data…, is the first level
- Dataset name, e.g. austin_bikeshare, is the second level
To restrict to one dataset:
options='{"url": "bigquery://project-XXXXXX/dataset_name"}'
Supporting additional connection parameters:
options='{"url": "bigquery://", "use_query_cache": "true"}'
Materialize
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install psycopg2

  or

./build/env/bin/pip install psycopg2-binary
Then give Hue the information about the database source:
[[[postgresql]]]
name = Materialize
interface=sqlalchemy
options='{"url": "postgresql://user:password@localhost:6875/"}'
Teradata
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install sqlalchemy-teradata
Then give Hue the information about the database source:
[[[teradata]]]
name = Teradata
interface=sqlalchemy
options='{"url": "teradata://user:password@localhost"}'
Alternative:
[[[teradata]]]
name=Teradata JDBC
interface=jdbc
options='{"url": "jdbc:teradata://localhost/database", "driver": "com.teradata.jdbc.TeraDriver", "user": "user", "password": "password"}'
DB2
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install ibm_db_sa
(or via https://github.com/ibmdb/python-ibmdbsa/tree/master/ibm_db_sa)
Then give Hue the information about the database source:
[[[db2]]]
name = DB2
interface=sqlalchemy
options='{"url": "db2+ibm_db://user:password@hostname[:port]/database"}'
Alternative:
[[[db2]]]
name=DB2 JDBC
interface=jdbc
options='{"url": "jdbc:db2://localhost:50000/database", "driver": "com.ibm.db2.jcc.DB2Driver", "user": "user", "password": "password"}'
Apache Spark SQL
This Spark SQL Editor post demoes the integration.
There are two ways to connect depending on your infrastructure:
Distributed SQL Engine
Hue supports two interfaces: SqlAlchemy and native Thrift. Native Thrift handles long-running queries better, but it might have some rough edges.
SqlAlchemy
With SqlAlchemy the dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install git+https://github.com/gethue/PyHive
Note: The SQLAlchemy interface requires the Hive connector, which does not work out of the box because of PyHive issue #150. Install the patched fork shown above.
This module might also be needed:
./build/env/bin/pip install thrift_sasl
Then give Hue the information about the database source:
[[[sparksql]]]
name=Spark SQL
interface=sqlalchemy
options='{"url": "hive://user:password@localhost:10000/database"}'
Distributed SQL Engine / Thrift Server
With the HiveServer Thrift (same as the one used by Hive and Impala so more robust depending on the use cases):
[spark]
# Host of the Spark Thrift Server
# https://spark.apache.org/docs/latest/sql-distributed-sql-engine.html
sql_server_host=localhost

# Port of the Spark Thrift Server
sql_server_port=10000
And make sure you have a sparksql interpreter configured:
[[[sparksql]]]
name=Spark SQL
interface=hiveserver2
Apache Livy
Apache Livy provides a bridge to a running Spark interpreter so that SQL, pyspark and Scala snippets can be executed interactively.
This Spark SQL Editor with Livy post demoes the integration.
[spark]
# The Livy Server URL.
livy_server_url=http://localhost:8998
And as always, make sure you have an interpreter configured:
[[[sparksql]]]
name=Spark SQL
interface=livy
Azure SQL Database
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install pyodbc
Then configure ODBC according to the documentation.
Then give Hue the information about the database source:
[[[azuresql]]]
name = Azure SQL Server
interface=sqlalchemy
options='{"url": "mssql+pyodbc://<user>@<server-host>:<password>@<server-host>.database.windows.net:1433/<database>?driver=ODBC+Driver+13+for+SQL+Server"}'
Note: Properties need to be URL quoted, for example with
urllib.parse.quote_plus(...)in Python.
Read more on the Azure SQL Database.
MS SQL Server
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install pymssql
Then give Hue the information about the database source:
[[[mssql]]]
name = SQL Server
interface=sqlalchemy
options='{"url": "mssql+pymssql://<username>:<password>@<freetds_name>/?charset=utf8"}'
Alternative:
Microsoft’s SQL Server JDBC drivers can be downloaded from the official site: Microsoft JDBC Driver
[[[sqlserver]]]
name=SQLServer JDBC
interface=jdbc
options='{"url": "jdbc:microsoft:sqlserver://localhost:1433", "driver": "com.microsoft.jdbc.sqlserver.SQLServerDriver", "user": "admin", "password": "pass"}'
Vertica
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install sqlalchemy-vertica-python
Then give Hue the information about the database source:
[[[vertica]]]
name = Vertica
interface=sqlalchemy
options='{"url": "vertica+vertica_python://user:pwd@localhost:port/database"}'
Alternative:
Be sure to download the Vertica’s JDBC client driver for the right version and OS.
[[[vertica]]]
name=Vertica JDBC
interface=jdbc
options='{"url": "jdbc:vertica://localhost:5433/example", "driver": "com.vertica.jdbc.Driver", "user": "admin", "password": "pass"}'
AWS Redshift
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install sqlalchemy-redshift
Then give Hue the information about the database source:
[[[redshift]]]
name = Redshift
interface=sqlalchemy
options='{"url": "redshift+psycopg2://[email protected]:5439/database"}'
Apache Drill
The dialect is available on https://github.com/JohnOmernik/sqlalchemy-drill
Then give Hue the information about the database source:
[[[drill]]]
name = Drill
interface=sqlalchemy
options='{"url": "drill+sadrill://..."}'
## To use Drill with SQLAlchemy you will need to craft a connection string in the format below:
# drill+sadrill://<username>:<password>@<host>:<port>/<storage_plugin>?use_ssl=True
## To connect to Drill running on a local machine running in embedded mode you can use the following connection string.
# drill+sadrill://localhost:8047/dfs?use_ssl=False
Alternative:
The Drill JDBC driver can be used.
[[[drill]]]
  name=Drill JDBC
  interface=jdbc
  ## Specific options for connecting to the server.
  ## The JDBC connectors, e.g. mysql.jar, need to be in the CLASSPATH environment variable.
  ## If 'user' and 'password' are omitted, they will be prompted in the UI.
  options='{"url": "<drill-jdbc-url>", "driver": "org.apache.drill.jdbc.Driver", "user": "admin", "password": "admin"}'
SAP Sybase
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install python-sybase
Then give Hue the information about the database source:
[[[sybase]]]
name = Sybase
interface=sqlalchemy
options='{"url": "sybase+pysybase://<username>:<password>@<dsn>/[database name]"}'
SAP Hana
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install sqlalchemy-hana
(or via https://github.com/SAP/sqlalchemy-hana)
Then give Hue the information about the database source:
[[[hana]]]
name = SAP HANA
interface=sqlalchemy
options='{"url": "hana://username:[email protected]:30015"}'
Apache Solr
SQL
Query Solr collections like you would query a regular database via Solr SQL.
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install sqlalchemy-solr
(or via https://github.com/aadel/sqlalchemy-solr)
Then give Hue the information about the database source:
[[[solr]]]
name = Solr SQL
interface=sqlalchemy
options='{"url": "solr://<username>:<password>@<host>:<port>/solr/<collection>[?use_ssl=true|false]"}'
Note
There is also a native implementation, which has some caveats. It reuses the [search] configuration of the Dashboards.
First make sure Solr is configured for Dashboards, as described below.
Then add the interpreter:
[[[solr]]]
name = Solr SQL
interface=solr
## Name of the collection handler
# options='{"collection": "default"}'
Dashboards
Hue ships dynamic dashboards for exploring datasets visually. Just point to an existing Solr server:
[search]
# URL of the Solr Server
solr_url=http://localhost:8983/solr/

# Requires FQDN in solr_url if enabled
## security_enabled=false

## Query sent when no term is entered
## empty_query=*:*
Apache Kylin
Apache Kylin is an open-source online analytical processing (OLAP) engine. See how to configure the Kylin Query Editor.
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install kylinpy
Then give Hue the information about the database source:
[[[kylin]]]
name = Kylin
interface=sqlalchemy
options='{"url": "kylin://..."}'
Alternative:
[[[kylin]]]
name=kylin JDBC
interface=jdbc
options='{"url": "jdbc:kylin://172.17.0.2:7070/learn_kylin", "driver": "org.apache.kylin.jdbc.Driver", "user": "ADMIN", "password": "KYLIN"}'
Dask SQL
dask-sql adds a SQL layer on top of Dask. It uses the Presto wire protocol for communication, so the SqlAlchemy dialect for Presto should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install pyhive
Then give Hue the information about the database source:
[[[dasksql]]]
name=Dask SQL
interface=sqlalchemy
options='{"url": "presto://localhost:8080/catalog/default"}'
Clickhouse
The sqlalchemy-clickhouse dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install sqlalchemy-clickhouse
Then give Hue the information about the database source:
[[[clickhouse]]]
name = Clickhouse
interface=sqlalchemy
# e.g. clickhouse://user:[email protected]:8124/test?protocol=https
options='{"url": "clickhouse://localhost:8123"}'
If you get an error like:
ModuleNotFoundError: No module named 'connector'
Update pytz:
./build/env/bin/pip install pytz==2021.1
Alternative:
[[[clickhouse]]]
name=ClickHouse
interface=jdbc
## Specific options for connecting to the ClickHouse server.
## The JDBC driver clickhouse-jdbc.jar and its related jars need to be in the CLASSPATH environment variable.
options='{"url": "jdbc:clickhouse://localhost:8123", "driver": "ru.yandex.clickhouse.ClickHouseDriver", "user": "readonly", "password": ""}'
Apache Kyuubi
Apache Kyuubi is a distributed and multi-tenant gateway to provide serverless SQL on data warehouses and lakehouses.
Give Hue the information about the database source:
[[[kyuubi]]]
name=Kyuubi
interface=jdbc
## Specific options for connecting to the Kyuubi server.
## The JDBC driver kyuubi-hive-jdbc-shaded.jar and its related jars need to be in the CLASSPATH environment variable.
options='{"url": "jdbc:hive2://localhost:10009", "driver": "org.apache.kyuubi.jdbc.KyuubiHiveDriver", "user": "readonly", "password": ""}'
Elastic Search
The dialect for https://github.com/elastic/elasticsearch should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install elasticsearch-dbapi
Then give Hue the information about the database source:
[[[es]]]
name = Elastic Search
interface=sqlalchemy
options='{"url": "elasticsearch+http://localhost:9200/"}'
Apache Pinot DB
The dialect for https://pinot.apache.org should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install pinotdb
Then give Hue the information about the database source:
[[[pinot]]]
name = Pinot
interface=sqlalchemy
options='{"url": "pinot+http://localhost:8099/query?server=http://localhost:9000/"}'
Snowflake
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install snowflake-sqlalchemy
Then give Hue the information about the database source:
[[[snowflake]]]
name = Snowflake
interface=sqlalchemy
options='{"url": "snowflake://{user}:{password}@{account}/{database}"}'
Note: account is the name in your URL domain. e.g.
https://smXXXXXX.snowflakecomputing.com/ --> smXXXXXX
Tables currently need to be prefixed with a schema, e.g. SELECT * FROM tpch_sf1.customer LIMIT 5
e.g.
options='{"url": "snowflake://hue:pwd@smXXXXX/SNOWFLAKE_SAMPLE_DATA"}'
Read more about is on the snowflake-sqlalchemy page.
Sqlite
Just give Hue the information about the database source:
[[[sqlite]]]
name = Sqlite
interface=sqlalchemy
options='{"url": "sqlite:///path/to/database.db"}'
Google Sheets
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install gsheetsdb
Then give Hue the information about the database source:
[[[gsheets]]]
name = Google Sheets
interface=sqlalchemy
options='{"url": "gsheets://"}'
Read more on the gsheetsdb page.
Greenplum
The dialect should be added to the Python system or Hue Python virtual environment:
./build/env/bin/pip install psycopg2
Then give Hue the information about the database source:
[[[greenplum]]]
name = Greenplum
interface=sqlalchemy
options='{"url": "postgresql+psycopg2://user:password@localhost:31335/database"}'
Storage
HDFS
Hue supports one HDFS cluster. That cluster should be defined under the [[[default]]] sub-section.
[hadoop]

# Configuration for HDFS NameNode
# ------------------------------------------------------------------------
[[hdfs_clusters]]

[[[default]]]
fs_defaultfs=hdfs://hdfs-name-node.com:8020
webhdfs_url=http://hdfs-name-node.com:20101/webhdfs/v1
HA is supported by pointing to the HttpFs service instead of the NameNode.
Make sure the HDFS service has in it hdfs-site.xml:
<property>
  <name>dfs.webhdfs.enable</name>
  <value>true</value>
</property>
Configure Hue as a proxy user for all other users and groups, meaning it may submit a request on behalf of any other user:
WebHDFS: Add to core-site.xml:
<!-- Hue WebHDFS proxy user setting -->
<property>
<name>hadoop.proxyuser.hue.hosts</name>
<value>*</value>
</property>
<property>
<name>hadoop.proxyuser.hue.groups</name>
<value>*</value>
</property>
HttpFS: Verify that /etc/hadoop-httpfs/conf/httpfs-site.xml has the following configuration:
<!-- Hue HttpFS proxy user setting -->
<property>
<name>httpfs.proxyuser.hue.hosts</name>
<value>*</value>
</property>
<property>
<name>httpfs.proxyuser.hue.groups</name>
<value>*</value>
</property>
If the configuration is not present, add it to /etc/hadoop-httpfs/conf/httpfs-site.xml and restart the HttpFS daemon. Verify that core-site.xml has the following configuration:
<property>
<name>hadoop.proxyuser.httpfs.hosts</name>
<value>*</value>
</property>
<property>
<name>hadoop.proxyuser.httpfs.groups</name>
<value>*</value>
</property>
If the configuration is not present, add it to /etc/hadoop/conf/core-site.xml and restart Hadoop.
Apache Ozone
Hue can read and write files on the Ozone filesystem, similar to HDFS. Add the following settings in the [[ozone]] section under [desktop]:
[desktop]
[[ozone]]
[[[default]]]
fs_defaultfs=ofs://[***SERVICE-ID***]
webhdfs_url=http://[***OZONE-HTTPFS-HOST***]:[***OZONE-HTTPFS-PORT***]/webhdfs/v1
ssl_cert_ca_verify=true
security_enabled=true
Where:
- fs_defaultfs: Ozone service ID (HA mode) or URL for Ozone Manager (non-HA mode).
- webhdfs_url: URL of HttpFS endpoint for the running Ozone service (
httpsfor secure service elsehttp).
Configure Hue as a proxy user for all other users and groups, so that it can submit requests on behalf of any other user.
In the Ozone service, verify or add the following configuration in httpfs-site.xml:
<!-- Hue HttpFS proxy user setting -->
<property>
<name>httpfs.proxyuser.hue.hosts</name>
<value>*</value>
</property>
<property>
<name>httpfs.proxyuser.hue.groups</name>
<value>*</value>
</property>
S3
The File Browser lets users explore, manage and upload data in an S3 account, in addition to HDFS and Ozone.
Read more in the S3 user documentation.
To add an S3 account, configure Hue with valid S3 credentials: the access key ID and the secret access key.
You can store the keys securely in scripts that print the key to stdout, in the same way as Hue reads password scripts. To use scripts, add the following section to hue.ini:
[aws]
[[aws_accounts]]
[[[default]]]
access_key_id_script=/path/to/access_key_script
secret_access_key_script=/path/to/secret_key_script
allow_environment_credentials=false
region=us-east-1
Alternatively, set the plain-text values of your keys. Don't do this in production or secure environments:
[aws]
[[aws_accounts]]
[[[default]]]
access_key_id=s3accesskeyid
secret_access_key=s3secretaccesskey
allow_environment_credentials=false
region=us-east-1
Set region to the AWS region of the S3 account. When it is not set, Hue falls back to us-east-1 (or to the region of the EC2 instance). region is ignored when host is set.
Using Ceph
To use an S3-compatible service such as Ceph, set host to its endpoint. You can also set is_secure and calling_format.
Azure File Systems
The File Browser lets users explore, manage and upload data in ADLS v1 or ADLS v2 (ABFS), in addition to HDFS, Ozone and S3.
To add an Azure account, configure Hue with valid Azure credentials: the client ID, client secret and tenant ID. Add them to hue.ini:
[azure]
[[azure_accounts]]
[[[default]]]
client_id=adlsclientid
client_secret=adlsclientsecret
tenant_id=adlstenantid
Then set the account name used by ADLS or ABFS in the same [azure] section:
[azure]
[[adls_clusters]]
[[[default]]]
fs_defaultfs=adl://<account_name>.azuredatalakestore.net
webhdfs_url=https://<account_name>.azuredatalakestore.net/webhdfs/v1

[[abfs_clusters]]
[[[default]]]
fs_defaultfs=abfs://<container_name>@<account_name>.dfs.core.windows.net
webhdfs_url=https://<account_name>.dfs.core.windows.net
GCS
The File Browser can explore and manage Google Cloud Storage buckets (gs://) with a service account. For development, you can store its JSON credentials in plain text:
[desktop]
[[gc_accounts]]
[[[default]]]
json_credentials='{ "type": "service_account", "project_id": .... }'
HBase
Specify the comma-separated list of HBase Thrift servers for clusters in the format of “(name|host:port)":
[hbase]
hbase_clusters=(Cluster|localhost:9090)
Impersonation
doAs Impersonation provides a flexible way to use the same client to impersonate multiple principals. doAs is supported only in Thrift 1. Enable doAs support by adding the following properties to hbase-site.xml on each Thrift gateway:
<property>
  <name>hbase.regionserver.thrift.http</name>
  <value>true</value>
</property>
<property>
  <name>hbase.thrift.support.proxyuser</name>
  <value>true</value>
</property>
And the Hue hosts, or * to authorize from any host:
<property>
  <name>hadoop.proxyuser.hbase.hosts</name>
  <value>*</value>
</property>
<property>
  <name>hadoop.proxyuser.hbase.groups</name>
  <value>*</value>
</property>
Note: If you use framed transport, you can't use doAs impersonation, because SASL does not work with Thrift framed transport.
Kerberos cluster
In a secure cluster, you also need these properties:
<property>
  <name>hbase.thrift.spnego.principal</name>
  <value>HTTP/<hostname_from_above>@REALM</value>
  </property>
<property>
  <name>hbase.thrift.spnego.keytab.file</name>
  <value>hbase.keytab</value>
</property>
And from the HBase shell, authorize some ends users, e.g. to give full access to admin:
hbase shell> grant 'admin', 'RWXCA'
Metadata
Apache Atlas
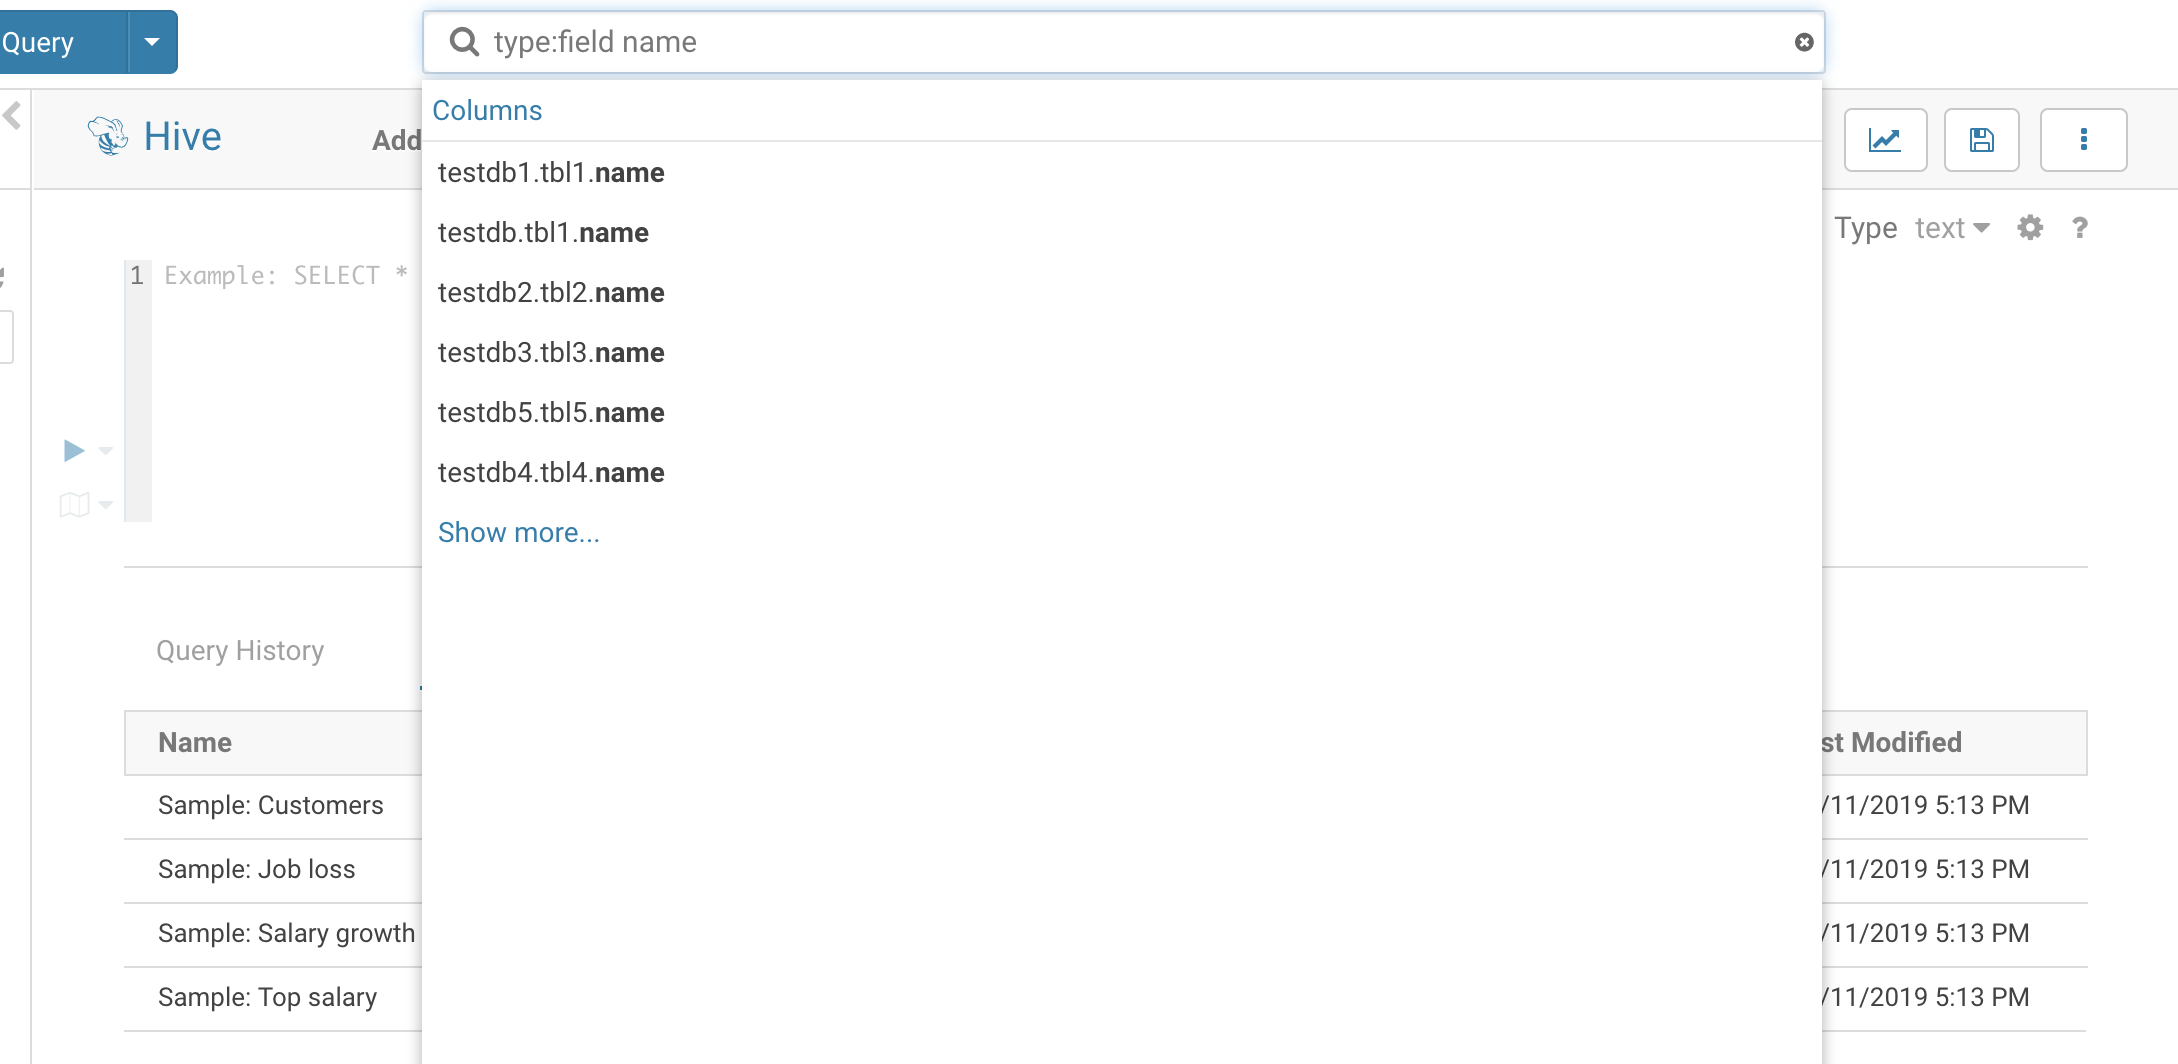
In the [metadata] section, Hue supports Apache Atlas and Cloudera Navigator to enrich the data catalog.
[metadata]
[[catalog]]
# The type of Catalog: Apache Atlas, Cloudera Navigator...
interface=atlas
# Catalog API URL (without version suffix).
api_url=http://localhost:21000/atlas/v2

# Username used for authentication.
## server_user=hue
# Password of the user used for authentication.
server_password=

# Limits found entities to a specific cluster. When empty the entities from all clusters will be included in the search results.
## search_cluster=

# Set to true when authenticating via kerberos instead of username/password
## kerberos_enabled=false
Cloudera Navigator
The Apache Atlas integration replaces this one, which is deprecated but still available in the [[navigator]] section.
Cloudera Navigator Optimizer
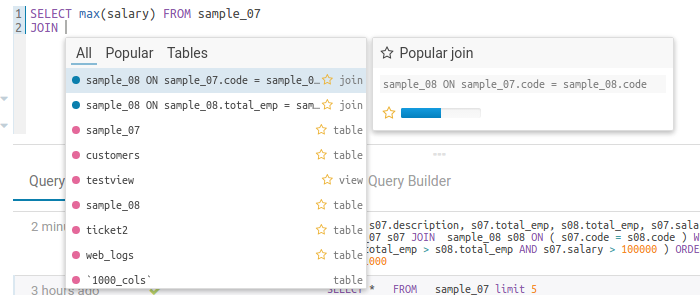
The integration powers the Risk Alerts and Popular Values in the SQL Autocomplete.
Jobs
Apache Spark
This connector uses the Apache Livy REST Api.
In the [[interpreters]] section:
[[[pyspark]]]
name=PySpark
interface=livy

[[[sparksql]]]
name=SparkSql
interface=livy

[[[spark]]]
name=Scala
interface=livy

[[[r]]]
name=R
interface=livy
In the [spark] section:
[spark]
# The Livy Server URL.
livy_server_url=http://localhost:8998
Make sure the Notebook app is not blocked and is shown in the menu:
[desktop]
app_blacklist=

[notebook]
show_notebooks=true
YARN: Spark session could not be created
If you see an error similar to this one with primitiveMkdir:
The Spark session could not be created in the cluster: at org.apache.hadoop.io.retry.RetryInvocationHandler$Call.invokeMethod(RetryInvocationHandler.java:165)
at org.apache.hadoop.io.retry.RetryInvocationHandler$Call.invoke(RetryInvocationHandler.java:157)
at org.apache.hadoop.io.retry.RetryInvocationHandler$Call.invokeOnce(RetryInvocationHandler.java:95)
at org.apache.hadoop.io.retry.RetryInvocationHandler.invoke(RetryInvocationHandler.java:359) at com.sun.proxy.$Proxy10.mkdirs(Unknown Source)
at org.apache.hadoop.hdfs.DFSClient.primitiveMkdir(DFSClient.java:2333) ... 20 more
19/05/13 12:27:07 INFO util.ShutdownHookManager: Shutdown hook called 19/05/13 12:27:07 INFO util.ShutdownHookManager:
Deleting directory /tmp/spark-0d045154-77a0-4e12-94b2-2df18725a4ae YARN Diagnostics:
Check that your logged-in user has a home directory on HDFS, for example /user/bob. The Livy or YARN logs show the full error.
In the Hue user admin, edit the user, select Create home directory and save.
CSRF
Livy has a CSRF protection setting in its configuration:
livy.server.csrf-protection.enabled
It is false by default. If you enable it in Livy, launching a Livy session from the Editor fails with a 400 response: “Missing Required Header for CSRF protection”. To fix it, add this to the Hue configuration:
[spark]
# Whether Livy requires client to use csrf protection.
csrf_enabled=true
Impersonation
To create a shell that runs as the user bob, send this request to Livy. This is useful when multiple users share a Notebook server:
curl -X POST --data '{"kind": "pyspark", "proxyUser": "bob"}' -H "Content-Type: application/json" localhost:8998/sessions
Livy returns:
{"id":0,"state":"starting","kind":"pyspark","proxyUser":"bob","log":[]}
Add the user running Hue (your login in development, hue in production) to the Hadoop proxy user list in /etc/hadoop/conf/core-site.xml:
<property>
  <name>hadoop.proxyuser.hue.hosts</name>
  <value>*</value>
</property>
<property>
  <name>hadoop.proxyuser.hue.groups</name>
  <value>*</value>
</property>
Apache Pig
Pig is native to Hue and depends on the Oozie service being configured:
[[[pig]]]
name=Pig
interface=oozie
Apache Oozie
To schedule workflows, set the Oozie URL in the [liboozie] section:
[liboozie]
oozie_url=http://oozie-server.com:11000/oozie
Make sure that the Share Lib is installed.
To configure Hue as a default proxy user, add the following properties to /etc/oozie/conf/oozie-site.xml:
<!-- Default proxyuser configuration for Hue -->
<property>
    <name>oozie.service.ProxyUserService.proxyuser.hue.hosts</name>
    <value>*</value>
</property>
<property>
    <name>oozie.service.ProxyUserService.proxyuser.hue.groups</name>
    <value>*</value>
</property>
Apache YARN
Hue supports one or two Yarn clusters (two for HA). These clusters should be defined
under the [[[default]]] and [[[ha]]] sub-sections.
# Configuration for YARN (MR2)
# ------------------------------------------------------------------------
[[yarn_clusters]]

[[[default]]]

resourcemanager_host=yarn-rm.com
resourcemanager_api_url=http://yarn-rm.com:8088/
proxy_api_url=http://yarn-proxy.com:8088/
resourcemanager_port=8032
history_server_api_url=http://yarn-rhs-com:19888/
Apache Sentry
To point Hue to a Sentry service, set these hue.ini properties:
[libsentry]
# Hostname or IP of server.
hostname=localhost

# Port the sentry service is running on.
port=8038

# Sentry configuration directory, where sentry-site.xml is located.
sentry_conf_dir=/etc/sentry/conf
Hue also picks up the HiveServer2 server name from the sentry-site.xml file in /etc/hive/conf.
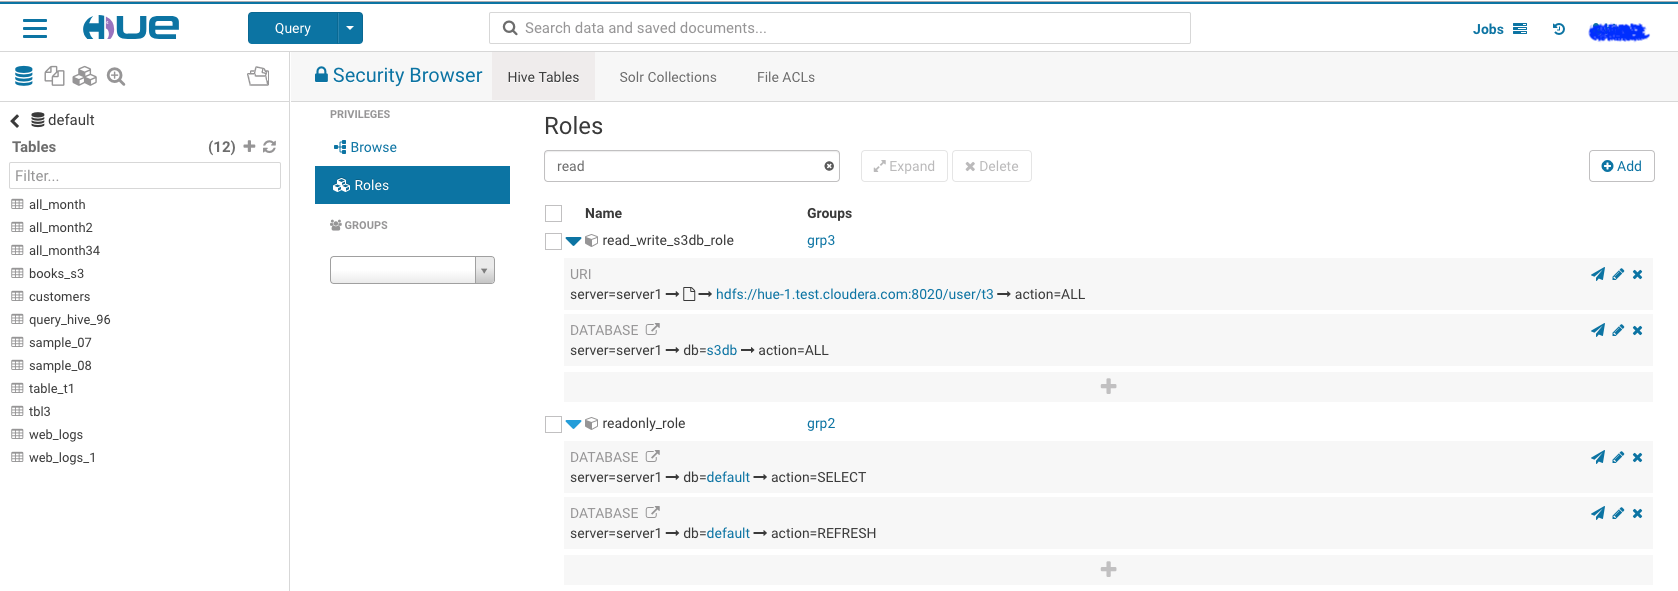
Users can then manage privileges in the Hue web UI. The app uses the standard Sentry API.
To edit roles and privileges in Hue, the logged-in Hue user must belong to a group in Hue that is also an admin group in Sentry. Whatever group mapping Sentry uses, the corresponding groups must exist in Hue or be entered manually. For example, the hive user belongs to a hive group in Hue and to a hive group in Sentry:
<property>
  <name>sentry.service.admin.group</name>
  <value>hive,impala,hue</value>
</property>
Follow these steps:
- Create a role in the Sentry app through Hue
- Grant privileges to that role such that the role can see the database in the Sentry app
- Create a group in Hue with the same name as the role in Sentry
- Grant that role to a user in Hue
- Ensure that the user has an operating system account on all hosts, and that the account belongs to a group with the same name as the group in Hue. This assumes that HDFS uses the default
ShellBasedUnixGroupsMapping.
In this example, the users are:
hive(admin) belongs to thehivegroupuser1_1belongs to theuser_group1groupuser2_1belongs to theuser_group2group
Sync the Unix users and groups into Hue with this command:
./build/env/bin/hue useradmin_sync_with_unix --min-uid=1000
If you use Kerberos, make sure the hue user can connect to Sentry in /etc/sentry/conf/sentry-site.xml:
<property>
  <name>sentry.service.allow.connect</name>
  <value>impala,hive,solr,hue</value>
</property>
Here is an example sentry-site.xml:
<?xml version="1.0" encoding="UTF-8"?>
<configuration>
<property>
  <name>sentry.service.security.mode</name>
  <value>none</value>
</property>
<property>
  <name>sentry.service.admin.group</name>
  <value>hive,romain</value>
</property>
<property>
  <name>sentry.service.allow.connect</name>
  <value>impala,hive,solr</value>
</property>
<property>
  <name>sentry.store.jdbc.url</name>
  <value>jdbc:derby:;databaseName=sentry_store_db;create=true</value>
</property>
<property>
  <name>sentry.store.jdbc.driver</name>
  <value>org.apache.derby.jdbc.EmbeddedDriver</value>
</property>
<property>
  <name>sentry.store.jdbc.password</name>
  <value>aaa</value>
</property>
</configuration>
Apache Knox
To let Hue trust requests that come through Apache Knox, set these properties:
[desktop]
[[knox]]

# This is a list of hosts that knox proxy requests can come from
## knox_proxyhosts=server1.domain.com,server2.domain.com

# List of Kerberos principal name which is allowed to impersonate others
## knox_principal=knox1,knox2

# Comma separated list of strings representing the ports that the Hue server can trust as knox port.
## knox_ports=80,8443